[ Mission control ▸ Applied AI ]
Measuring what AI gets right
I build tools around Claude Code and local models, then measure how often they're right.
Mission 01 ▸ Local research MCP Operational
Your GPU answers first
Claude Code hands codebase questions to a local 27B model, checks the citations, and takes back only what it gets wrong.
- Eval score
- 70% Claude Sonnet 5.5 ▸ 71%
- Hallucination
- 13% down from 26%
- Claude tokens
- 0 per local answer
MCP-01 ▸ Ground station ▸ one question, start to finish
Claude sends a code question to the local model instead of reading the files itself.
The model searches an index of 1,395 Lua files and reads only what it needs.
The answer comes back with citations, each marked as read or unverified.
Medium-confidence answers and Java engine questions go up the relay to Claude.
Mission 02 ▸ Name TBD Pre-launch
Can you trust Claude's market calls?
Claude writes three briefs every trading day, every call is sealed in a hash-chained log, and a paper portfolio scores it against SPY and random picks.
- Daily runs
- 3 08:30 ▸ 12:30 ▸ 16:30 ET
- Edits allowed
- 0 append-only, hash-chained
- Status
- M0 of M6 ▸ decisions
Paper only. It never trades. An experiment, not financial advice.
[ Also in orbit ]
Other projects
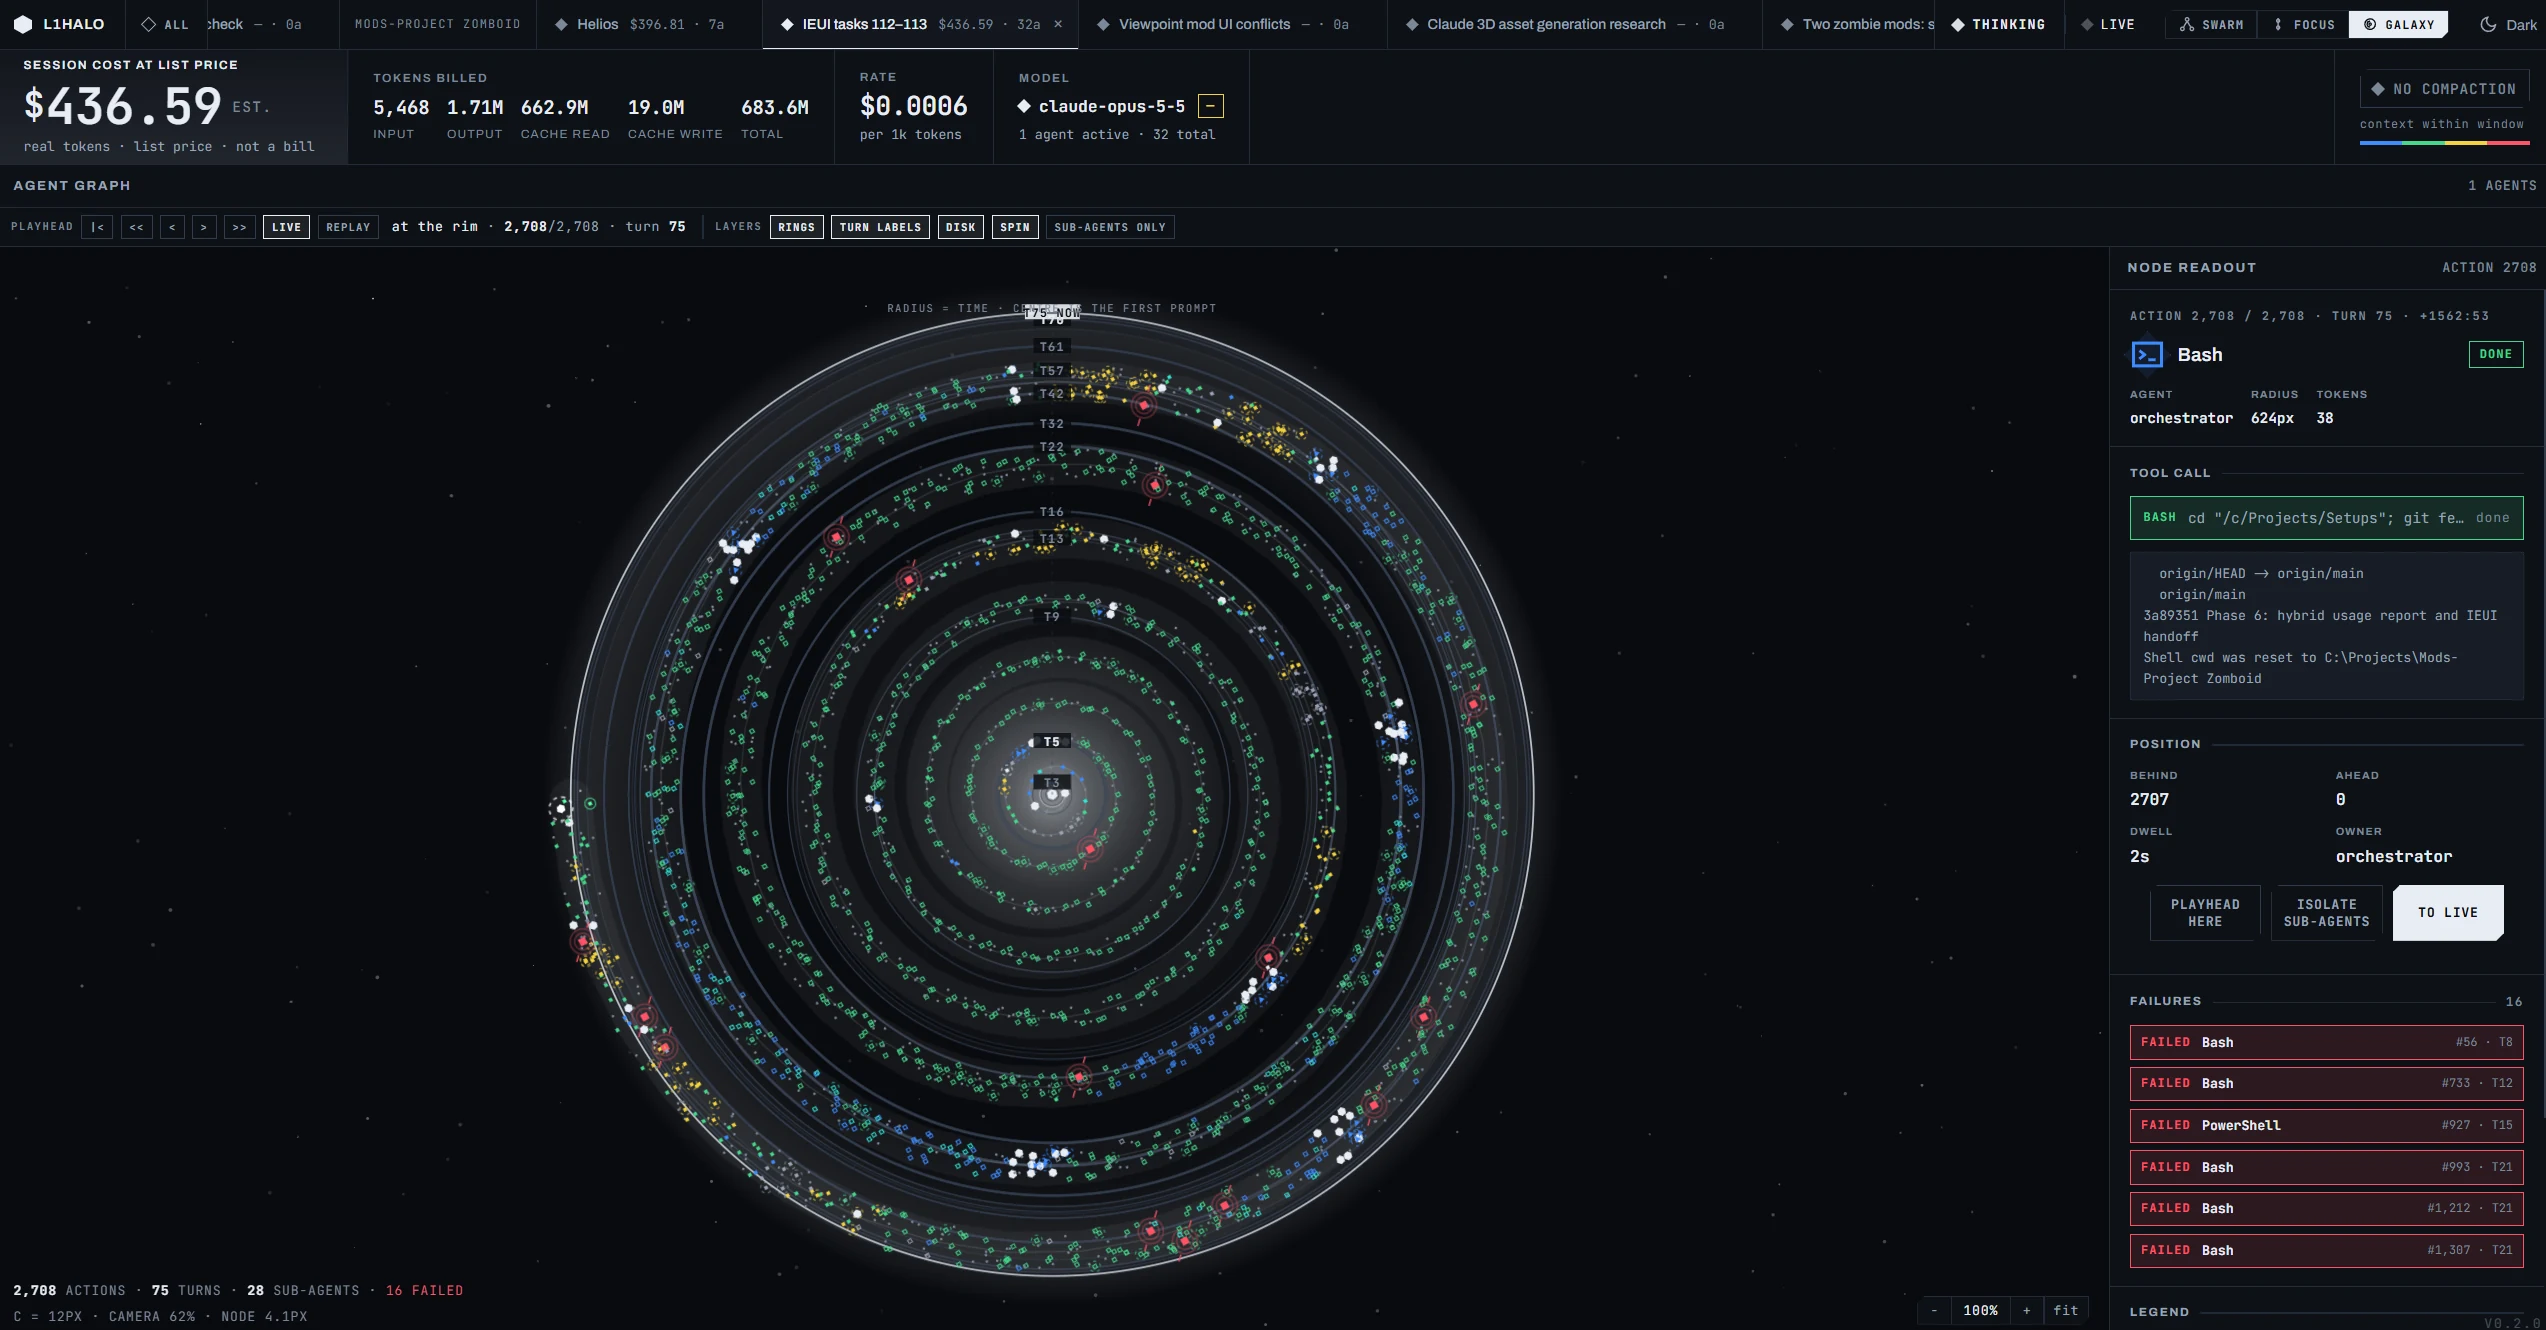 AUX-03 ▸ Desktop app
L1halo
A live map of Claude Code sessions, their sub-agents and their cost.
Open ▸
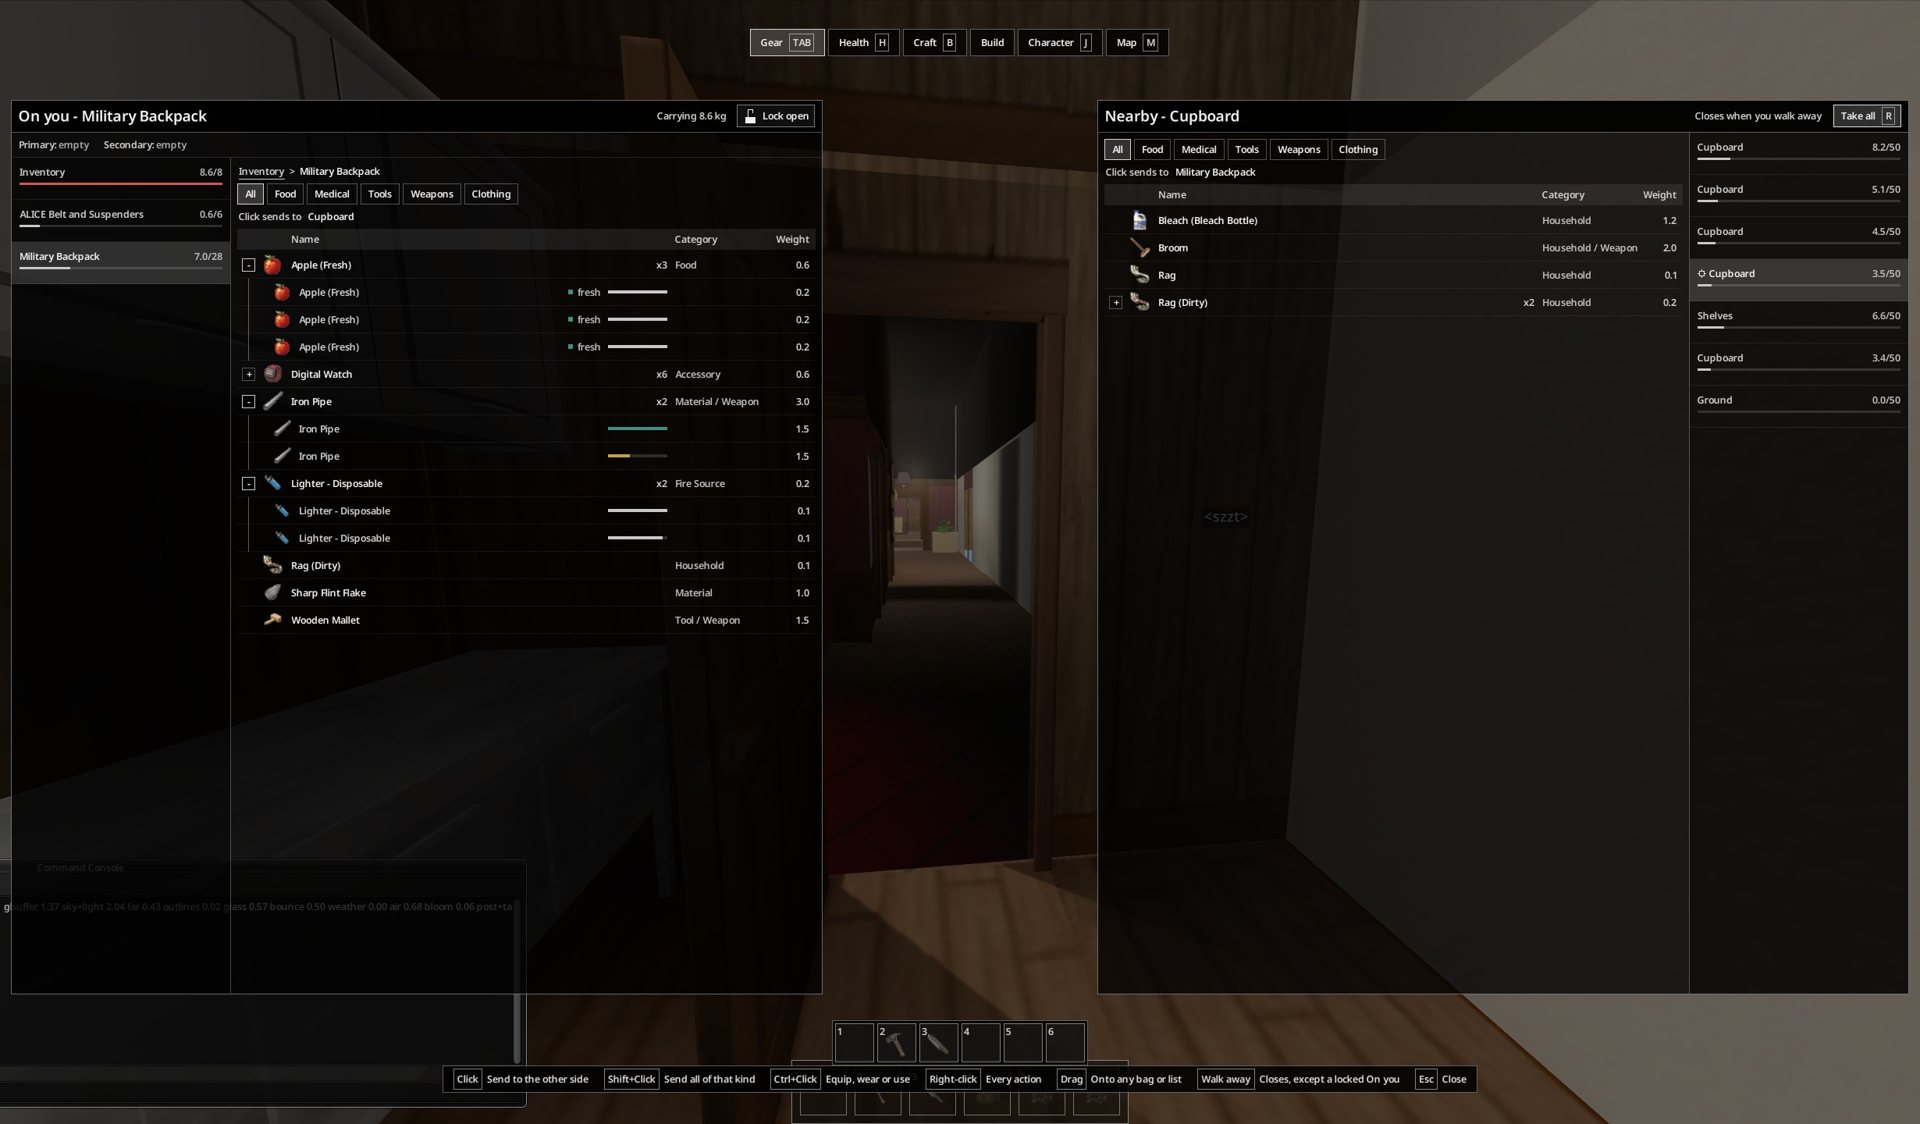 AUX-04 ▸ Game mods
Project Zomboid mods
First-person inventory screens and five gameplay mods for Build 42.
Open ▸